Paper-Conference

Omnilingual MT: Machine Translation for 1,600 Languages featured image

Omnilingual MT: Machine Translation for 1,600 Languages

Outstanding Paper Award at EMNLP 2026. We present Omnilingual MT, the first MT system benchmarked on more than 1,600 languages, where 1B–8B parameter specialized models match or …

Belen Alastruey
•
Read more
BOUQuET: dataset, Benchmark and Open initiative for Universal Quality Evaluation in Translation featured image

BOUQuET: dataset, Benchmark and Open initiative for Universal Quality Evaluation in Translation

We introduce BOUQuET, a multi-way, multicentric, multi-domain, paragraph-level dataset and benchmark for machine translation evaluation, designed for crowd-sourced expansion to …

Pierre Andrews
•
Read more
Improving Language and Modality Transfer in Translation by Character-level Modeling featured image

Improving Language and Modality Transfer in Translation by Character-level Modeling

We propose a character-based translation model to improve adaptability to new languages and modalities, particularly for low-resource scenarios. Our method achieves …

Ioannis Tsiamas
•
Read more
Masked Generative Video-to-Audio Transformers with Enhanced Synchronicity featured image

Masked Generative Video-to-Audio Transformers with Enhanced Synchronicity

We propose MaskVAT, a generative Video-to-Audio (V2A) model combining a high-quality audio codec with a masked generative model to simultaneously achieve high audio quality, …

Santiago Pascual
•
Read more
Speech Is More than Words: Do Speech-to-Text Translation Systems Leverage Prosody? featured image

Speech Is More than Words: Do Speech-to-Text Translation Systems Leverage Prosody?

We investigate whether speech-to-text translation systems utilize prosody by introducing a new benchmark, ContraProSt. Our findings show that while models represent prosody …

Ioannis Tsiamas
•
Read more
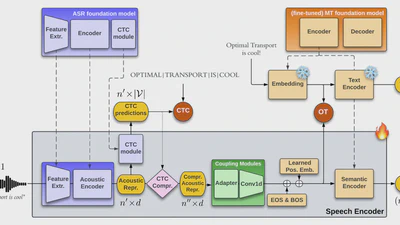
Pushing the Limits of Zero-shot End-to-End Speech Translation featured image

Pushing the Limits of Zero-shot End-to-End Speech Translation

We introduce ZeroSwot, a zero-shot speech translation method that aligns a speech encoder with a multilingual MT model using only ASR data, achieving state-of-the-art results …

Ioannis Tsiamas
•
Read more
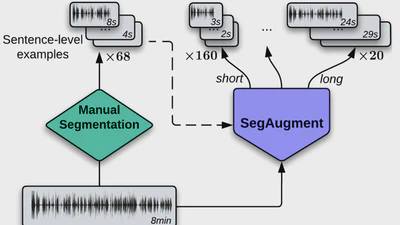
SegAugment: Maximizing the Utility of Speech Translation Data with Segmentation-based Augmentations featured image

SegAugment: Maximizing the Utility of Speech Translation Data with Segmentation-based Augmentations

We propose SegAugment, a data augmentation strategy that creates multiple sentence-level variations from document-level speech data, leading to significant performance gains in …

Ioannis Tsiamas
•
Read more
Speech Translation with Foundation Models and Optimal Transport: UPC at IWSLT23 featured image

Speech Translation with Foundation Models and Optimal Transport: UPC at IWSLT23

This paper details our submission to the IWSLT 2023 Speech Translation task, which utilizes wav2vec 2.0 and mBART50 foundation models. Our method incorporates a Siamese pretraining …

Ioannis Tsiamas
•
Read more
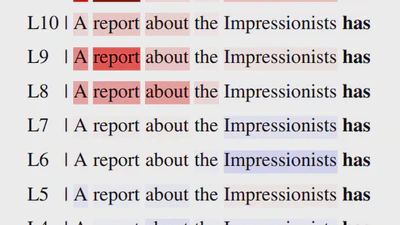
Explaining How Transformers Use Context to Build Predictions featured image

Explaining How Transformers Use Context to Build Predictions

We present a new method to explain how Transformer models use context for language generation, demonstrating superior alignment with linguistic phenomena and shedding light on the …

Javier Ferrando
•
Read more
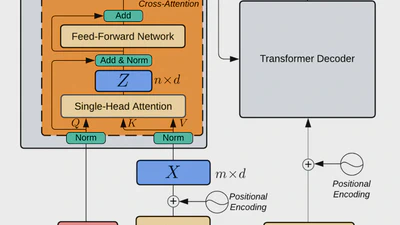
Efficient Speech Translation with Dynamic Latent Perceivers featured image

Efficient Speech Translation with Dynamic Latent Perceivers

We propose a Perceiver-based encoder with a novel Dynamic Latent Access (DLA) training method for efficient Speech Translation. This approach maps long speech inputs to a …

Ioannis Tsiamas
•
Read more
SHAS: Approaching optimal Segmentation for End-to-End Speech Translation featured image

SHAS: Approaching optimal Segmentation for End-to-End Speech Translation

We propose Supervised Hybrid Audio Segmentation (SHAS), a method that learns optimal speech segmentation from manually segmented data. SHAS significantly improves translation …

Ioannis Tsiamas
•
Read more
Pretrained Speech Encoders and Efficient Fine-tuning Methods for Speech Translation: UPC at IWSLT 2022 featured image

Pretrained Speech Encoders and Efficient Fine-tuning Methods for Speech Translation: UPC at IWSLT 2022

Our submission to the IWSLT 2022 shared task details an end-to-end speech translation system built on large pretrained models. We leverage efficient fine-tuning techniques like …

Ioannis Tsiamas
•
Read more

The TALP-UPC Participation in WMT21 News Translation Task: an mBART-based NMT Approach

Our submission to the WMT 2021 news translation shared task for German-French translation demonstrates that fine-tuning a pretrained mBART50 model significantly outperforms a …

Carlos Escolano
•
Read more
End-to-End Speech Translation with Pre-trained Models and Adapters: UPC at IWSLT 2021 featured image

End-to-End Speech Translation with Pre-trained Models and Adapters: UPC at IWSLT 2021

Our submission to the IWSLT 2021 shared task details an end-to-end speech translation system combining large pretrained models with adapters for efficient fine-tuning. By training …

Gerard I. Gállego
•
Read more