Speech Translation

Robust and Data-Efficient End-to-End Speech Translation: Segmentation, Cross-Modal Alignment, and Prosody-Aware Evaluation

My PhD thesis (Excellent, cum laude): robust segmentation, data augmentation, zero-shot cross-modal alignment, and prosody-aware evaluation for end-to-end speech translation.

Ioannis Tsiamas
•
Read more
Omnilingual SONAR: Cross-Lingual and Cross-Modal Sentence Embeddings Bridging Massively Multilingual Text and Speech featured image

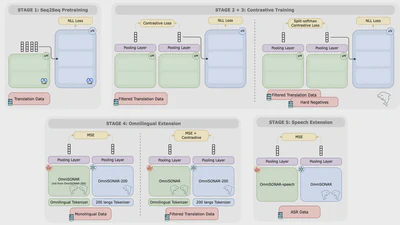
Omnilingual SONAR: Cross-Lingual and Cross-Modal Sentence Embeddings Bridging Massively Multilingual Text and Speech

We introduce OmniSONAR, a family of omnilingual cross-lingual and cross-modal sentence embedding models spanning 4,000+ language varieties and natively supporting text, speech, …

The Omnilingual SONAR Team
•
Read more
Improving Language and Modality Transfer in Translation by Character-level Modeling featured image

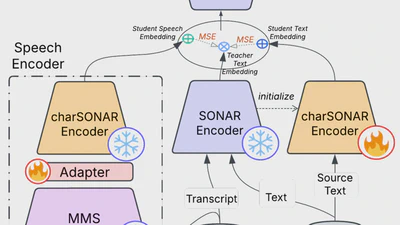
Improving Language and Modality Transfer in Translation by Character-level Modeling

We propose a character-based translation model to improve adaptability to new languages and modalities, particularly for low-resource scenarios. Our method achieves …

Ioannis Tsiamas
•
Read more
Speech Is More than Words: Do Speech-to-Text Translation Systems Leverage Prosody? featured image

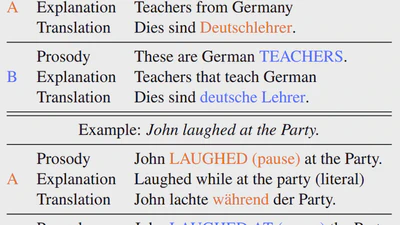
Speech Is More than Words: Do Speech-to-Text Translation Systems Leverage Prosody?

We investigate whether speech-to-text translation systems utilize prosody by introducing a new benchmark, ContraProSt. Our findings show that while models represent prosody …

Ioannis Tsiamas
•
Read more
Pushing the Limits of Zero-shot End-to-End Speech Translation featured image

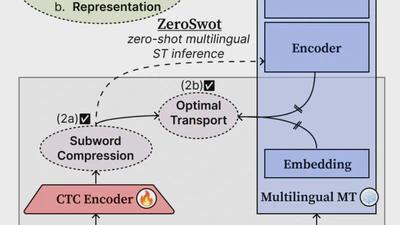
Pushing the Limits of Zero-shot End-to-End Speech Translation

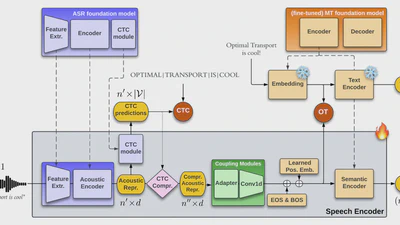
We introduce ZeroSwot, a zero-shot speech translation method that aligns a speech encoder with a multilingual MT model using only ASR data, achieving state-of-the-art results …

Ioannis Tsiamas
•
Read more
SegAugment: Maximizing the Utility of Speech Translation Data with Segmentation-based Augmentations featured image

SegAugment: Maximizing the Utility of Speech Translation Data with Segmentation-based Augmentations

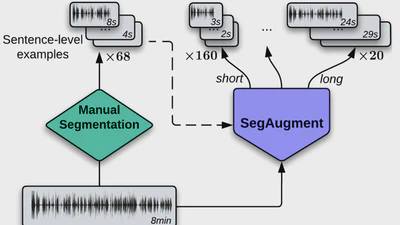
We propose SegAugment, a data augmentation strategy that creates multiple sentence-level variations from document-level speech data, leading to significant performance gains in …

Ioannis Tsiamas
•
Read more
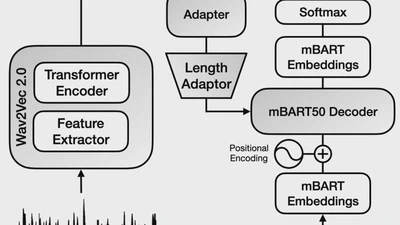
Speech Translation with Foundation Models and Optimal Transport: UPC at IWSLT23 featured image

Speech Translation with Foundation Models and Optimal Transport: UPC at IWSLT23

This paper details our submission to the IWSLT 2023 Speech Translation task, which utilizes wav2vec 2.0 and mBART50 foundation models. Our method incorporates a Siamese pretraining …

Ioannis Tsiamas
•
Read more
Efficient Speech Translation with Dynamic Latent Perceivers featured image

Efficient Speech Translation with Dynamic Latent Perceivers

We propose a Perceiver-based encoder with a novel Dynamic Latent Access (DLA) training method for efficient Speech Translation. This approach maps long speech inputs to a …

Ioannis Tsiamas
•
Read more
SHAS: Approaching optimal Segmentation for End-to-End Speech Translation featured image

SHAS: Approaching optimal Segmentation for End-to-End Speech Translation

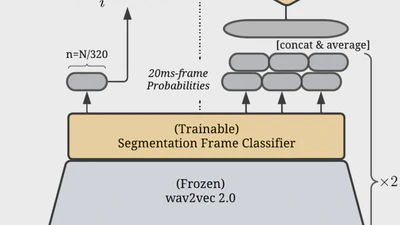
We propose Supervised Hybrid Audio Segmentation (SHAS), a method that learns optimal speech segmentation from manually segmented data. SHAS significantly improves translation …

Ioannis Tsiamas
•
Read more
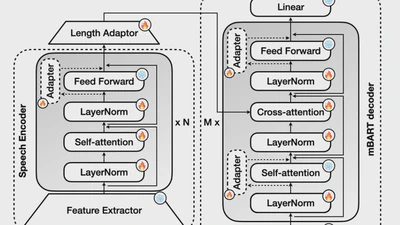
Pretrained Speech Encoders and Efficient Fine-tuning Methods for Speech Translation: UPC at IWSLT 2022 featured image

Pretrained Speech Encoders and Efficient Fine-tuning Methods for Speech Translation: UPC at IWSLT 2022

Our submission to the IWSLT 2022 shared task details an end-to-end speech translation system built on large pretrained models. We leverage efficient fine-tuning techniques like …

Ioannis Tsiamas
•
Read more
End-to-End Speech Translation with Pre-trained Models and Adapters: UPC at IWSLT 2021 featured image

End-to-End Speech Translation with Pre-trained Models and Adapters: UPC at IWSLT 2021

Our submission to the IWSLT 2021 shared task details an end-to-end speech translation system combining large pretrained models with adapters for efficient fine-tuning. By training …

Gerard I. Gállego
•
Read more